PRR: Predict, Reuse, and Repair
Accelerating Dynamic Sparse Attention for Long-Context LLM Decoding via Speculative Execution and Incremental Repair
PRR: Predict, Reuse, and Repair — Accelerating Dynamic Sparse Attention for Long-Context LLM Decoding
一、论文概述
| 项目 | 内容 |
|---|---|
| 标题 | Predict, Reuse, and Repair: Accelerating Dynamic Sparse Attention for Long-Context LLM Decoding |
| 作者 | Tianyu Wang¹, Gourav Rattihalli², Aditya Dhakal², Junbo Li¹, Zhiwei Ren¹, Dejan Milojicic², Longfei Shangguan¹ |
| 机构 | ¹University of Pittsburgh, Pittsburgh, PA, USA; ²HPE Labs, Milpitas, CA, USA |
| 论文 | arXiv:2606.30389 |
| 代码 | github.com/Tianyu9748/Incremental_FlashAttention |
| 发布 | 29 Jun 2026 |
| 许可 | arXiv.org perpetual non-exclusive license |
二、核心思想
问题定义
动态稀疏注意力(Dynamic Sparse Attention, DSA)通过在每次解码步骤中选择与当前查询最相关的 top-K KV blocks 来加速长上下文 LLM 推理,显著减少了注意力计算量。然而,DSA 引入了一个新的瓶颈:selection-to-attention 依赖。在注意力计算运行之前,DSA 必须先执行压缩注意力并识别 top-K KV blocks。由于这些 block 的 ID 在选择完成前是未知的,注意力严格串行在选择之后。随着上下文长度增长,这种依赖成为越来越严重的延迟瓶颈——选择阶段占 per-token 生成延迟的比例从 16K token 时的约 60% 上升到 512K 时的 71%,单独的选择阶段就占用了高达 41% 的 per-token 生成延迟。
解决方案概述
PRR(Predict, Reuse, and Repair)是一种 speculate-reuse-repair 运行时,通过利用 DSA 选择中的 temporal locality 来打破 selection-to-attention 的串行依赖。其核心思路:
- 预测(Predict):使用轻量级的 EMA 预测器追踪 block 重要性的时间轨迹,anticipate(而非 lag)即将到来的 top-K 集合
- 重用(Reuse):对预测的 block 集 P 执行 speculative attention,与真正的选择过程并行
- 修复(Repair):一旦 true top-K 集合 A 已知,通过基于 FlashAttention 的 incremental repair kernel 将 missed blocks (A \ P) 合并到部分注意力结果中
PRR 的三个关键设计:
- Lightweight EMA-based predictor:利用 DSA 已产生的 importance scores,无需额外模型执行开销;在 prefill 阶段通过 grid search 按 prompt 校准超参数
- Profiling-guided speculation budget:离线 profile 不同上下文长度和预算比 δ 下的选择延迟和 speculative attention 延迟,构建查找表,运行时选择最大的安全 δ,确保 speculative execution 不延长 critical path
- FlashAttention-based repair kernel:基于 online-softmax recurrence 实现 incremental attention repair,将 post-selection 工作量从 |A| 缩减到 |M| = |A \ P|,保证与标准 DSA 完全相同的精度
动机发现
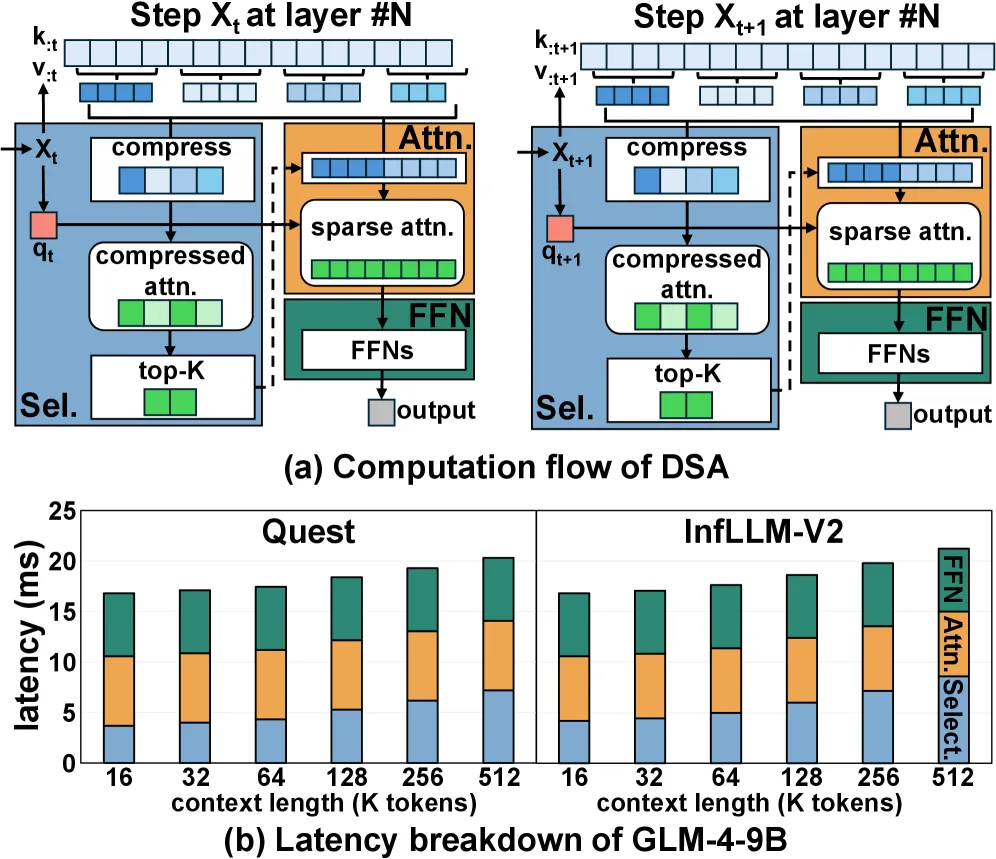
论文通过 profiling 发现了三个关键观察:
Observation One: DSA 显著减少了注意力计算,但暴露了 serialized selection-to-attention dependency。在 16K tokens 时 selection+attention 路径消耗约 60% 的 decoding latency,在 512K 时升至 71%。
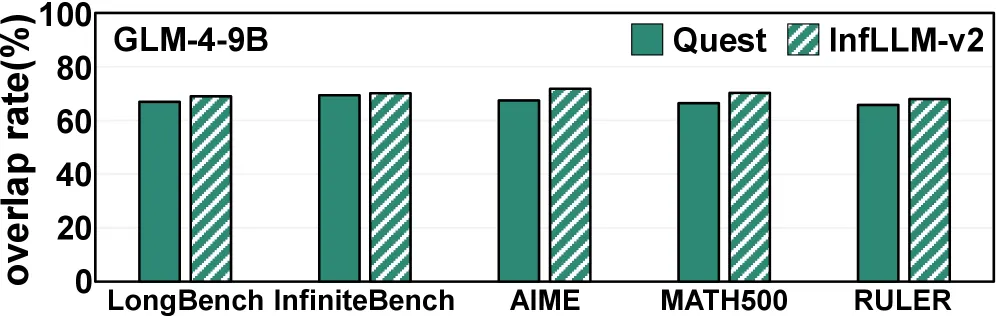
Observation Two: DSA 的 top-K blocks 在相邻解码步骤间表现出强局部性。在 LongBench、InfiniteBench、AIME、MATH500 和 RULER 五个基准上,Quest 和 InfLLM-V2 都一致地重选了超过 65% 的 blocks,平均重叠率约 68%。
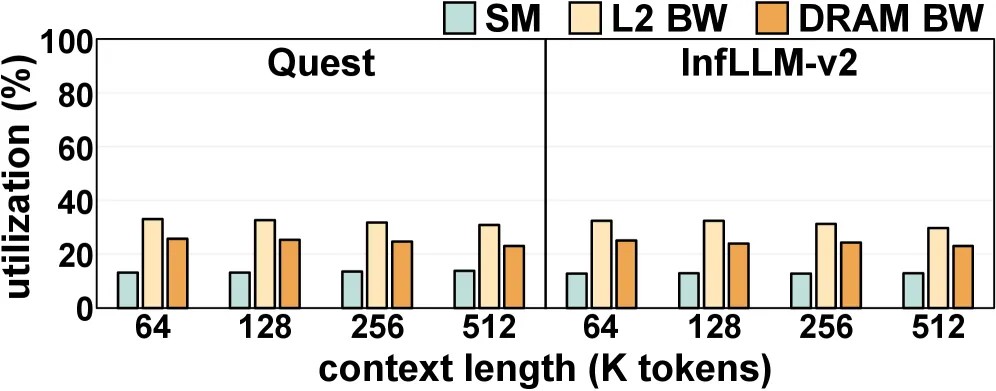
Observation Three: Long-context DSA decoding 留下了充足的空闲 GPU 资源。即使在 512K context length 下,SM、L2-bandwidth 和 DRAM-bandwidth 利用率均低于 40%,为 speculative KV gathering 和 attention computation 提供了充足的 headroom。
三、技术架构
整体框架图
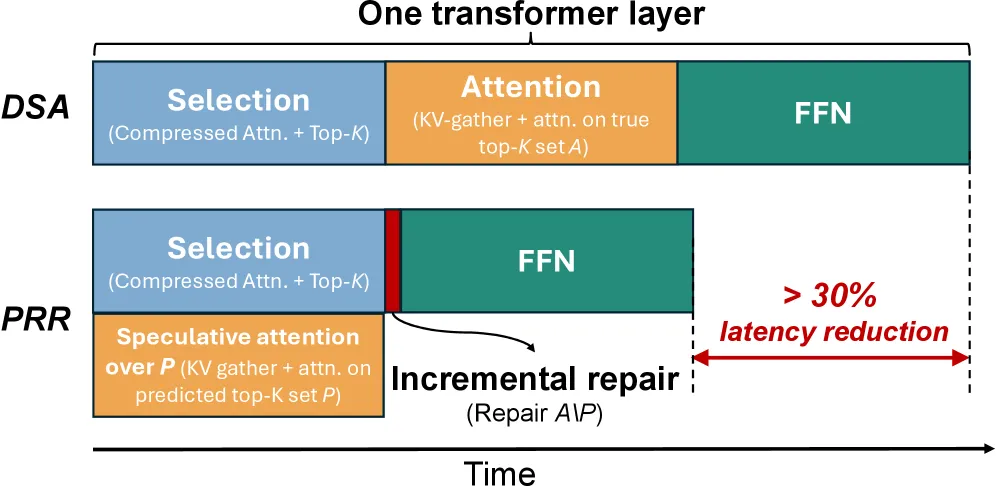
标准 DSA 串行执行 selection → attention over true top-K set A → FFN。PRR 则:
- 预测 block 集 P
- 在 selection 进行时并行执行 speculative attention over P
- Selection 完成后,仅对 missed blocks (A \ P) 执行 incremental repair
- 最后执行 FFN
每个 transformer layer 可节省超过 30% 的延迟。
核心公式
EMA Predictor
PRR 维护每个 block 在每一步 的两个状态变量:smoothed level 和 trend estimate 。当 block 在步骤 首次进入 KV cache 时,初始化 ,。
预测(Prediction):在步骤 开始时,在 DSA selection 产生真实分数 之前:
其中 控制预测器外推近期趋势的激进程度。
更新(Update):在步骤 的 DSA selection 产生真实分数 后:
这里 控制 level 跟随新分数的速度, 控制 trend estimate 适应分数变化的速度。
Online Predictor Calibration
Prefill trajectory:设 为 prefill token 数量。Prefill 阶段产生矩阵 ,其中行 是在 prefill token 处 个 dynamic blocks 上的 compressed-attention score vector。
Calibration objective:给定候选超参数 ,模拟预测器在 上运行,产生每个 prefill token 的 predicted selection set ,测量 score-weighted hit rate:
其中 是 prefill token 处的 ground-truth top-K block selection set。Per-prompt 超参数选择:
Search procedure:Grid search over (step 0.2)、(step 0.1)、(step 0.25),共 80 个候选。搜索与 prefill 阶段并行,仅增加 0.06 ms 额外延迟。
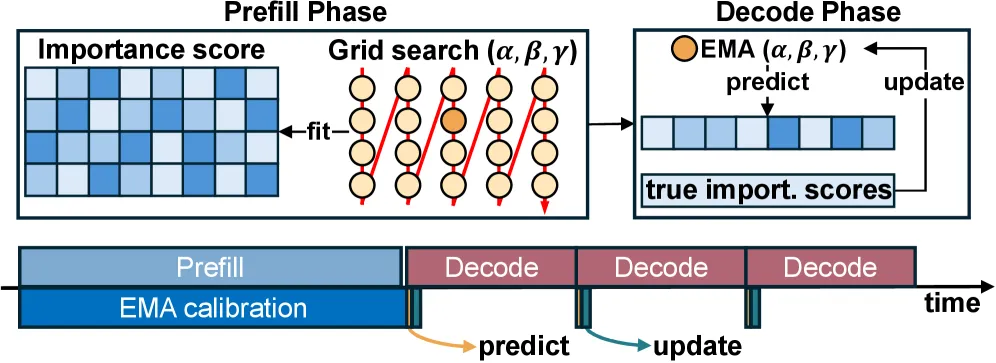
Incremental Attention Repair
Speculative attention 输出 和 missed blocks 的 KV 条目。Repair kernel 对每个 missed block 应用一次 online-softmax recurrence:
其中 和 是 missed block 的局部 max 和 sum。每个 query 独立处理,missed blocks 以 tiled fashion 流式处理,不 materialize intermediate score matrix。Kernel 读取 、、 和 missed tiles 各一次,写入修正后的 各一次。FLOPs 和 memory traffic 均只与 成比例。
Instrumented speculative kernel:修改 FlashAttention forward 以写入 output 以及 denominator 和 running maximum 到 HBM。额外存储仅为每 head 两个标量,kernel 保持原始 forward 的 memory-access pattern 和 occupancy。
设计空间
Design Space One: Maximize speculative attention accuracy. 将预测误差分为两类:
- Missed Blocks ():位于 critical path,每个 missed block 必须在 selection 完成后迁移和 attend
- Wasted Blocks ():消耗额外 bandwidth 和 compute,但不延长 critical path
优化目标为带预算约束的单目标问题:
其中 是 speculation budget ratio。
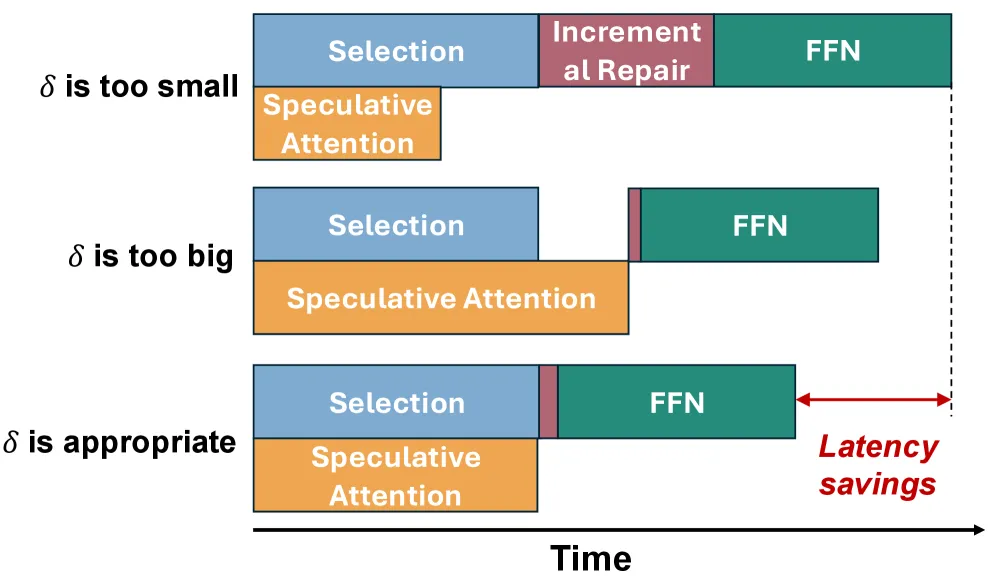
Design Space Two: Enable incremental attention repair。 简单 fallback(丢弃 speculative result 重新计算)会将 attention 放回 critical path,抵消 speculation 的延迟收益。PRR 的 incremental repair kernel 保证完整覆盖 true selected set A,同时将 post-selection 工作量从 缩减到 。
五大组件总结
| 组件 | 说明 | 关键特性 |
|---|---|---|
| EMA Predictor | 轻量级训练免费预测器,追踪 block importance 轨迹 | 三个超参数,per-prompt calibration |
| Online Calibration | Pre-fill 阶段 grid search 校准超参数 | 80 候选,0.06ms 开销,与 prefill 并行 |
| Speculation Budget | Profile-guided 动态预算控制 | 离线 profile 查找表,runtime 按上下文长度查表 |
| Speculative Attention | 对预测集 P 并行执行 attention | 修改 FlashAttention forward 额外写入 |
| Incremental Repair | FlashAttention-based CUDA kernel 修复 missed blocks | Online-softmax recurrence,精度无损 |
四、核心创新
| 创新点 | 说明 | 理论/实验依据 |
|---|---|---|
| 发现 selection-to-attention bottleneck | 首次系统分析 DSA 中新的 critical-path 依赖 | Section 2 profiling:selection 占比随上下文长度从 4ms 增至 8ms,占总延迟 41% |
| EMA-based predictor | 训练免费、超轻量的 block selection 预测器,优于 naive “reuse previous step” | Table 4:Quest 下 98.05% overlap,InfLLM-v2 下 97.52% |
| Online-softmax incremental repair | 首个支持将 missed blocks 增量合并到部分注意力结果的 kernel | 公式 (6)-(8),保证 full top-K coverage,post-selection 工作量与 $ |
| Profiling-guided dynamic budget | 离线 profile + runtime 查找表,动态调整 speculation budget | Figure 5: 太小则 repair 大,太大则 speculation 延迟 FFN |
五、代码实现分析
仓库结构
GitHub: https://github.com/Tianyu9748/Incremental_FlashAttention
Incremental_FlashAttention/
├── csrc/                    # CUDA source code (sparse FlashAttention fork)
├── hopper/                  # Hopper (H100) specific optimizations
│                            #   Variable-kBlockN sparse FA-3 path
├── sparse_flash_attn_2/     # Sparse FlashAttention-2 implementation
├── benchmarks/              # Benchmark scripts
├── roofline/                # Roofline analysis and utilization artifacts
├── tests/                   # Correctness tests
└── examples/inference/      # Inference examples
该仓库基于 sparse FlashAttention fork,针对 NVIDIA Hopper 架构进行了专门优化,包含 variable-kBlockN sparse FA-3 path。
实现要点
- Speculative kernel:修改 FlashAttention forward,在 inner-loop arithmetic 不变的前提下,额外写入两个标量( 和 )到 HBM
- Repair kernel:基于 FlashAttention online-softmax recurrence 的自定义 CUDA kernel,missed blocks 以 tiled fashion 流式处理
- Budget table:离线 profile 5 个上下文长度(4K/8K/16K/32K/64K),构建 lookup table
六、实验结果
实验设置
- 硬件:NVIDIA H100 GPUs,CUDA 12.8,tensor parallelism degree = 2
- Models:GLM-4-9B-1M, GLM-Z1-9B, DeepSeek-R1-8B, Llama3-8B-1M, Qwen3-14B, Qwen3-32B
- DSAs:QUEST(Tang et al. 2024)、InfLLM-v2(Zhao et al. 2025)
- Benchmarks:LongBench, InfiniteBench, RULER, AIME HuggingFace H4, MATH500
端到端加速效果
表1:PRR 相对 serial DSA 的解码加速比
| Model | Quest Avg | InfLLM-v2 Avg |
|---|---|---|
| GLM-4-9B | 1.42× | 1.56× |
| GLM-Z1-9B | 1.42× | 1.55× |
| DeepSeek-R1-8B | 1.41× | 1.44× |
| Llama3-8B | 1.38× | 1.43× |
| Qwen3-14B | 1.40× | 1.51× |
| Qwen3-32B | 1.28× | 1.31× |
整体平均:Quest 下 1.35×,InfLLM-v2 下 1.47×。最高达到 1.64×(GLM-4 on LongBench with InfLLM-v2)。
消融实验
表2:GLM-4-9B + InfLLM-v2 各组件贡献(相对 Serial 执行)
| Benchmark | S1: Reuse prev | S2: Repair Kernel | S3: Full PRR |
|---|---|---|---|
| LongBench | 1.02× | 1.34× | 1.64× |
| InfiniteBench | 1.00× | 1.19× | 1.38× |
| RULER | 1.01× | 1.34× | 1.58× |
| AIME | 1.02× | 1.34× | 1.62× |
| MATH500 | 1.01× | 1.31× | 1.59× |
| Avg | 1.01× | 1.30× | 1.56× |
关键发现:
- S1(仅 reuse previous step):几乎无改善(1.01×),因为 68% overlap 意味着 32% missed blocks 触发 full recomputation,抵消了 speculation 的收益
- S2(+ incremental repair kernel):提升至 1.30×,repair kernel 使 missed blocks 的修复成本大幅降低
- S3(+ EMA predictor):进一步提升至 1.56×,EMA 将 overlap rate 从 68% 提升到 98%
预测器命中率
表4:EMA 预测与真实 top-K 集合的重叠率(GLM-4-9B)
| Model | LongBench | InfiniteBench | RULER | AIME | MATH500 | Avg |
|---|---|---|---|---|---|---|
| Quest | 98.65% | 96.86% | 98.36% | 98.15% | 98.25% | 98.05% |
| InfLLM-v2 | 97.86% | 97.14% | 96.46% | 98.15% | 98.01% | 97.52% |
内核加速对比
表3:PRR sparse kernel vs FlashInfer BlockSparseAttention
| Block Size \ Token Budget | 1024 | 2048 | 4096 | 6144 | 8192 | Avg |
|---|---|---|---|---|---|---|
| 16 | 1.17× | 1.28× | 2.00× | 2.83× | 3.68× | 2.19× |
| 32 | 1.17× | 1.38× | 2.09× | 2.78× | 3.69× | 2.22× |
| 64 | 1.17× | 1.38× | 2.26× | 2.91× | 3.64× | 2.27× |
| 128 | 1.17× | 1.41× | 2.23× | 3.00× | 3.71× | 2.31× |
| 256 | 1.03× | 1.11× | 2.00× | 2.75× | 3.64× | 2.11× |
PRR kernel 在所有配置下均优于 BlockSparseAttention,平均加速 2.22×,峰值 3.71×(8K budget, block size 128)。在 1K tokens 时加速较小(1.03-1.17×),因为绝对延迟小且 fixed overheads 占主导。
七、相关工作
KV Cache Retrieval for DSA
FlexiCache 利用跨 heads 的 temporal stability(stable heads 保留 top-K KV pages,unstable heads 保留所有 pages),与 PRR 正交互补——PRR 利用跨 decoding steps 的 temporal locality。两者可组合:PRR 的 EMA predictor 可指导 FlexiCache stable heads 中保留哪些 pages。
LouisKV 和 AsyncSpade 通过 predict query state 来 prefetch relevant tokens,但 approximate query-state estimation 可能丢失 important tokens 而降质质量。PRR 基于 historical importance scores 的 temporal locality prefetch,并通过 attention repair 保证零精度损失。
Temporal Locality for KV Cache Management
Prior work (Lee et al. 2024; Levy 2026) 观察到相同 tokens 倾向于在连续解码步骤中被选中或获得高注意力分数,PRR 在此基础上进一步利用这一特性进行 speculative attention。
八、总结
核心贡献
- 发现新瓶颈:首次将 selection-to-attention dependency 识别为 DSA 中的 new critical-path bottleneck
- PRR 运行时:设计 speculate-reuse-repair 运行时,通过预测 predicted blocks 并并行执行 speculative attention,在 selection 完成后仅 repair missed blocks
- Incremental repair kernel:实现基于 online-softmax 的 custom CUDA kernel,保证 full top-K coverage(与标准 DSA 语义一致),同时将 post-selection 工作量 bound 在 missed blocks 数量内
- 系统性评估:在 6 个 LLM、2 个 DSA 方法、5 个 long-context benchmarks 上验证,平均加速 1.35×–1.56×
技术影响
- PRR 是 training-free 的,可直接叠加在任何 DSA 方法之上(Quest / InfLLM-v2)
- 不改变模型权重或训练流程,纯推理阶段优化
- 与现有 inference engines(vLLM, SGLang)和 attention kernels(FlashAttention, FlashInfer)兼容
局限性
- 仅评估 training-free DSA:未包含需训练的 NSA(需从头训练,计算资源消耗大)
- 仅优化 Hopper 架构:针对 NVIDIA Hopper(H100)和 half precision 优化,未来可扩展到 Blackwell 等架构和 fp8 等低精度
- Batch size = 1:仅评估单 request 场景,未来可探索 batch 内多 request 间的 stage coordination(block selection、speculation 协调)